Command Palette

Search for a command to run...

Open to Cloud & Infrastructure rolesSeattle, WA · Open to relocate

Hi, I'm Vidit Pawar · Cloud & Infrastructure Engineer

I build cloud platforms
that ship faster.

5+ years designing and operating multi-cloud platforms on AWS and Azure across payments, healthcare, and data infrastructure. Today I build infrastructure at Databricks: Terraform, Kubernetes, GitOps, and self-service tooling that keeps platform teams moving.

View Resume
Years in cloud & infrastructure
0+
Years in cloud & infrastructure
Availability under peak load
0.00%
Availability under peak load
Platform teams on self-service
0+
Platform teams on self-service
Repos behind security gates
0+
Repos behind security gates
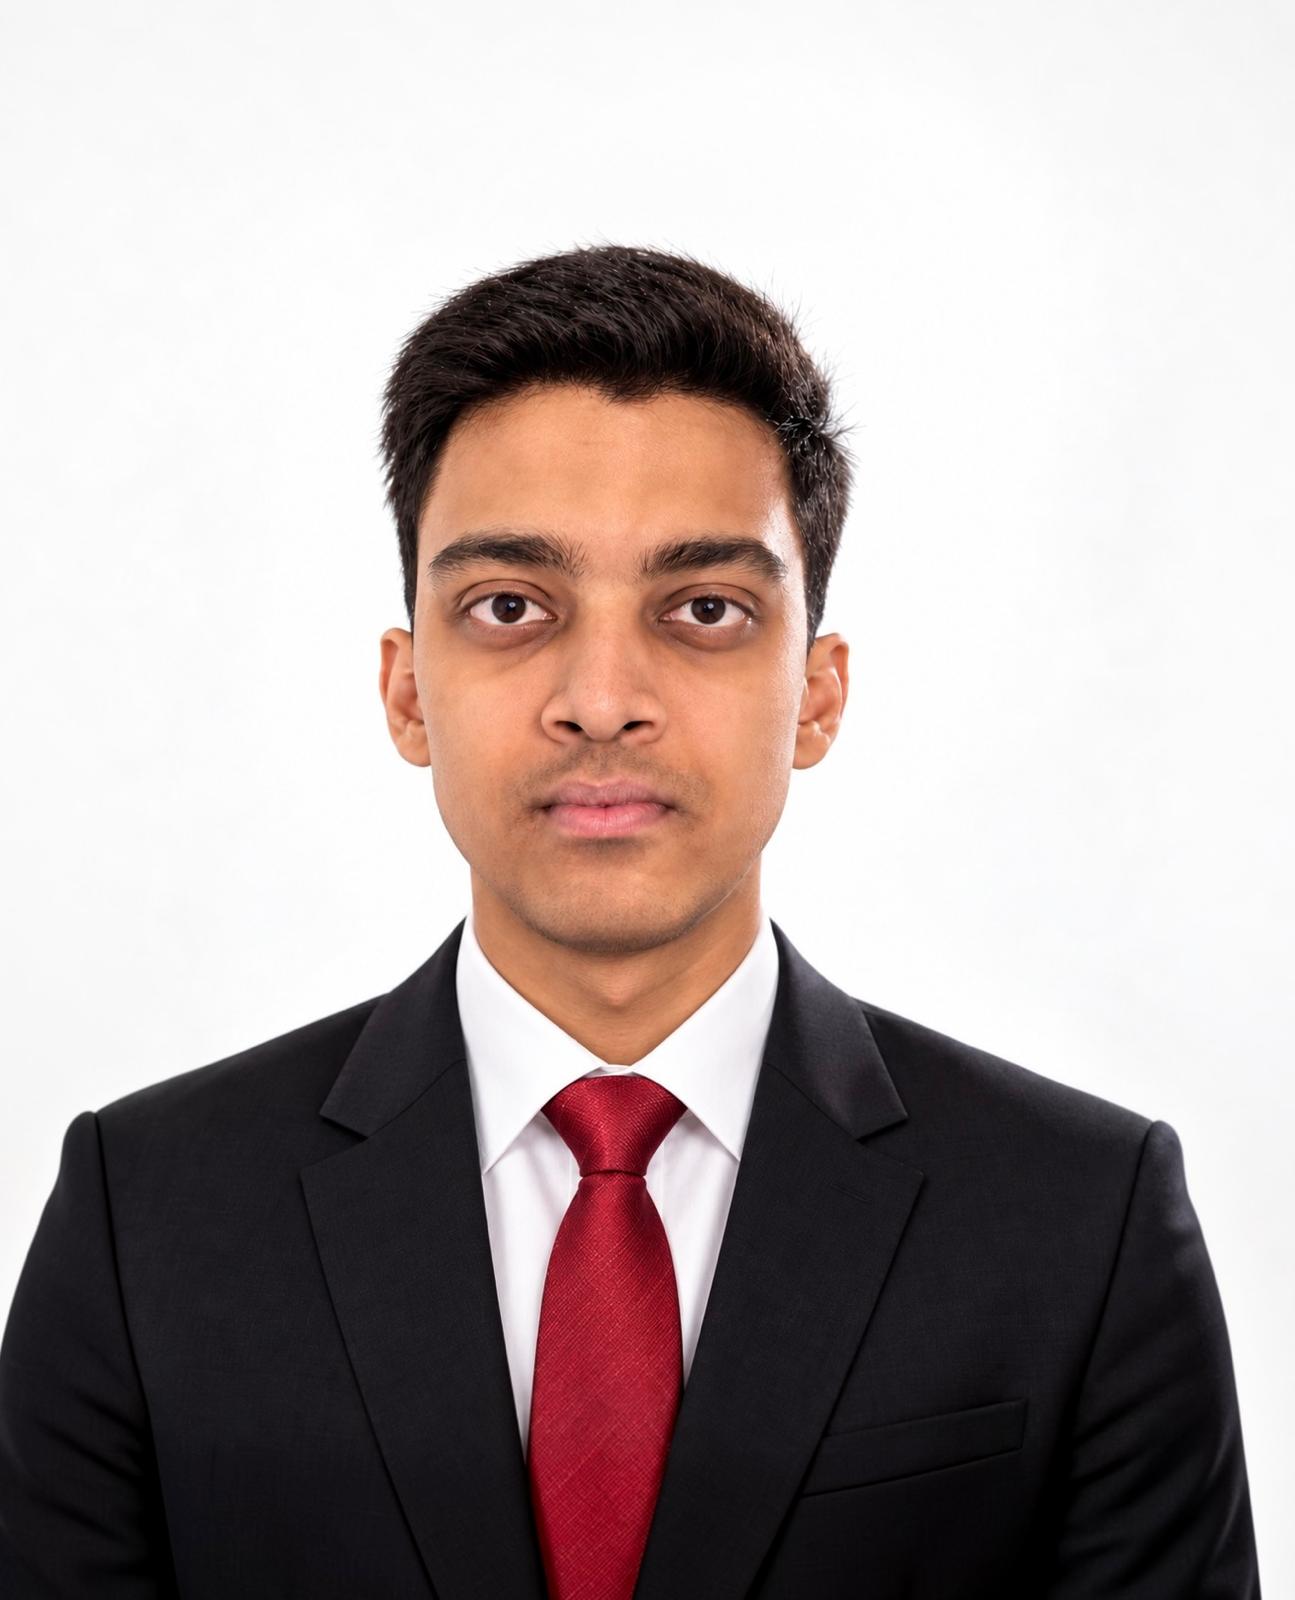
Portrait of Vidit Pawar

Vidit Pawar

Software Engineer

About

Platform engineering, end to end

I make cloud infrastructure repeatable, observable, and secure, so product teams can ship without thinking about it.

I started on call for PCI DSS-scoped payment services on Azure AKS, where I learned what a 15-minute restore SLA feels like at 2 a.m. At LTIMindtree I built a HIPAA-aligned AWS landing zone, migrated claims processing to EKS, and set up the monitoring that cut incident detection from 45 minutes to under 8. Now at Databricks I build the Terraform modules, self-service tooling, and GitOps delivery behind serverless compute.

Outside work I build the same way: self-healing Kubernetes controllers, SLO-driven data pipelines, and DevSecOps setups that gate every change on scans and tests.

Master of Science

Management Information Systems

University of Arizona

Aug 2024 – Dec 2025

Bachelor of Engineering

Electronics & Telecommunication

University of Mumbai

Jul 2018 – Jun 2022

Open toCloud EngineerInfrastructure EngineerPlatform EngineerDevOps EngineerSite Reliability Engineer
vidit@platform: ~
Welcome! Type help to see what you can explore, or click a command below.
➜~

Interactive. Try help, use ↑ for history and Tab to autocomplete.

Impact

Results, measured

Real before-and-after numbers from production systems I've worked on.

Before → after

Lower is better. Each row is scaled to its own starting point.

New-region rollout

Databricks · Terraform modules + Sentinel

3 weeks
< 2 days
−90%

Mean time to resolution

Databricks · Datadog tracing & SLOs

90 min
< 25 min
−72%

Analytics reporting latency

LTIMindtree · Airflow ETL to BigQuery

4 hrs
6 min
−98%

Mean time to detect

LTIMindtree · Prometheus & Grafana

45 min
< 8 min
−82%

Repetitive support tickets / week

Infinite Infolab · Lambda + Bash runbooks

40
15
−63%

Experience

Where I've worked

3 roles across payments, healthcare, and data infrastructure. Select a company to see what I shipped there.

Software Engineer, Infrastructure

Databricks · Data infrastructure

Aug 2025 – Present

Infrastructure behind serverless compute: Terraform-provisioned EKS, self-service environment tooling for platform teams, GitOps delivery, and SLO-driven reliability.

3 wks → <2 days

New-region rollout

99.95%

Availability under peak load

90 → <25 min

Mean time to resolution

  • Architected reusable Terraform modules with remote state and policy-as-code (Sentinel) to provision Amazon EKS infrastructure underlying serverless compute, cutting new-region rollout from three weeks to under two days.
  • Engineered a Python and FastAPI self-service API with an internal CLI that let 40+ platform teams provision isolated environments without tickets, removing roughly 600 manual provisioning requests each quarter.
  • Deployed control-plane services on Kubernetes with Helm and Argo CD GitOps, adding horizontal autoscaling with multi-AZ failover that held 99.95% availability under peak query load.
  • Implemented distributed tracing and SLO-based alerting using Datadog, improving production incident investigation and reducing mean time to resolution (MTTR) from 90 minutes to under 25 minutes.
  • Partnered with the security team on IAM least-privilege roles, wiring Checkov and Trivy scans into GitHub Actions to block misconfigured resources before merge across 120+ repositories.
TerraformSentinelAmazon EKSPythonFastAPICLI AutomationKubernetesHelmArgo CDDatadogSLOsIAM Least PrivilegeCheckovTrivyGitHub Actions

Projects

Things I've built

Platform projects from my GitHub, built the way I'd run them in production: automated, observable, and gated on tests and security scans.

GoKubernetesObservabilityDevSecOps

Aegis: Self-Healing Kubernetes Platform

A Go controller that remediates unhealthy pods, with metrics-gated canary rollouts.

Why it exists

Crash-looping and stuck-Pending pods need someone to notice and intervene. Aegis detects and remediates them automatically, and makes every deploy prove itself before it gets full traffic.

  • Event-driven Go controller built on client-go informers that remediates CrashLoopBackOff pods and sweeps for pods stuck Pending past a timeout
  • Argo Rollouts canary (25% → analysis → 50% → 100%) gated on a Prometheus success-rate query
GoKubernetesHelmArgo RolloutsPrometheusGrafanaGitHub Actions
View code
PythonIaCObservabilityData Platform

govwatch: Government Data Ingestion Platform

A legislation and regulation pipeline run like a production service, with SLOs and self-healing.

Why it exists

Tools that reason over bills and regulations are only as good as the data under them. govwatch continuously ingests congress.gov and regulations.gov and proves its own completeness.

  • Incremental cursors, idempotent Postgres upserts, and a completeness auditor that reconciles upstream counts and re-ingests gaps (1,060 / 1,060 bills on a live backfill)
  • 99% SLO with multi-window burn-rate alerts, each unit-tested with promtool and linked to a runbook
PythonPostgreSQLTerraformHelmPrometheusGrafanaCheckovTrivy
View code
PythonData PlatformObservability

QuakeFlow: Real-Time Earthquake Data Platform

Streaming and batch pipelines on live USGS data that handle late and revised events correctly.

Why it exists

USGS keeps revising earthquakes for hours or days after the first report. A naive pipeline counts every revision as a new event; QuakeFlow keeps each distinct revision once and always exposes exactly one current version.

  • Kafka → Flink (validate, dedupe, dead-letter) → Spark into an Iceberg bronze/silver/gold lakehouse, with transactional Kafka writes and idempotent merges
  • Failure-tested: killed Flink workers, a six-minute Kafka outage, and killed Spark loads all recover with every revision stored exactly once
PythonKafkaFlinkSparkIcebergAirflowPrometheusGrafanaDocker
View code
JavaScriptDevSecOpsKubernetesObservability

Three-Tier DevSecOps on Kubernetes

End-to-end CI/CD with security gates and GitOps delivery, all self-hosted.

Why it exists

Security scanning is easy to skip when it lives outside the pipeline. This project puts code quality, dependency, config, and image scanning in the path to production.

  • Jenkins pipeline: test → SonarQube → Trivy (filesystem, Kubernetes config, and image scans) → build → deploy
  • Argo CD tracks the manifests for GitOps delivery to a multi-node kind cluster with ingress-nginx
JenkinsSonarQubeTrivyArgo CDKubernetesPrometheusDocker
View code
PythonIaCData PlatformDevSecOps

contribflow: Payroll Contribution Pipeline

Exactly-once 401(k) contribution ingestion across multiple payroll formats.

Why it exists

A dropped payroll file means savings never arrive; a double-posted one means clawbacks. contribflow normalizes, validates, and posts each contribution exactly once, even on resubmission.

  • Content-hashed, idempotent ingestion with one transaction per file and a reconciliation report for every upload
  • YAML-driven connectors for CSV and fixed-width provider formats, validated against census and annual deferral limits
PythonPostgreSQLTerraformHelmKubernetesPrometheusGrafanaGitHub Actions
View code

Approach

How I work

01

Self-service over tickets

If teams wait on a ticket, build the tool instead. A FastAPI self-service API and CLI at Databricks removed roughly 600 manual provisioning requests a quarter.

02

Security in the pipeline

Least-privilege IAM, plus Checkov and Trivy gates in GitHub Actions that block misconfigured resources before merge across 120+ repositories.

03

Observe before you need to

Tracing and SLO-based alerting cut MTTR from 90 to under 25 minutes. Prometheus and Grafana across 12 microservices cut detection from 45 to under 8.

04

Reusable infrastructure

Modules, remote state, and policy-as-code make the safe path the fast path. Reusable Terraform turned a three-week region rollout into under two days.

Skills

Technical toolkit

Filter the list, or click a skill to see where I've used it.

Cloud Platforms

Infrastructure as Code & Configuration

CI/CD, GitOps & Containers

Programming & Backend

Databases & Data Engineering

Observability & Reliability

Security & Compliance

Contact

Let's build something
reliable together.

I'm looking for Cloud, Infrastructure, Platform, and SRE roles and I'm open to relocating anywhere in the US. The fastest way to reach me is email.